Reading and writing files
MDAPY, OVITO and ASE read and write LAMMPS dumps, LAMMPS data files and extended XYZ of the same systems, from 4 000 to 2 million atoms. A program is timed only where it reads the positions that MDAPY wrote, or writes a file that MDAPY reads back as the system.
Results
A node of the Triton cluster of Aalto University, alone for the run: two Intel Xeon Gold 6248 (40 cores, two NUMA nodes), 191 GB, Linux. Python 3.13, MDAPY 2.0.0.dev0 built with GCC 12.3, OVITO 3.17.1 and ASE 3.29.0 from pip.
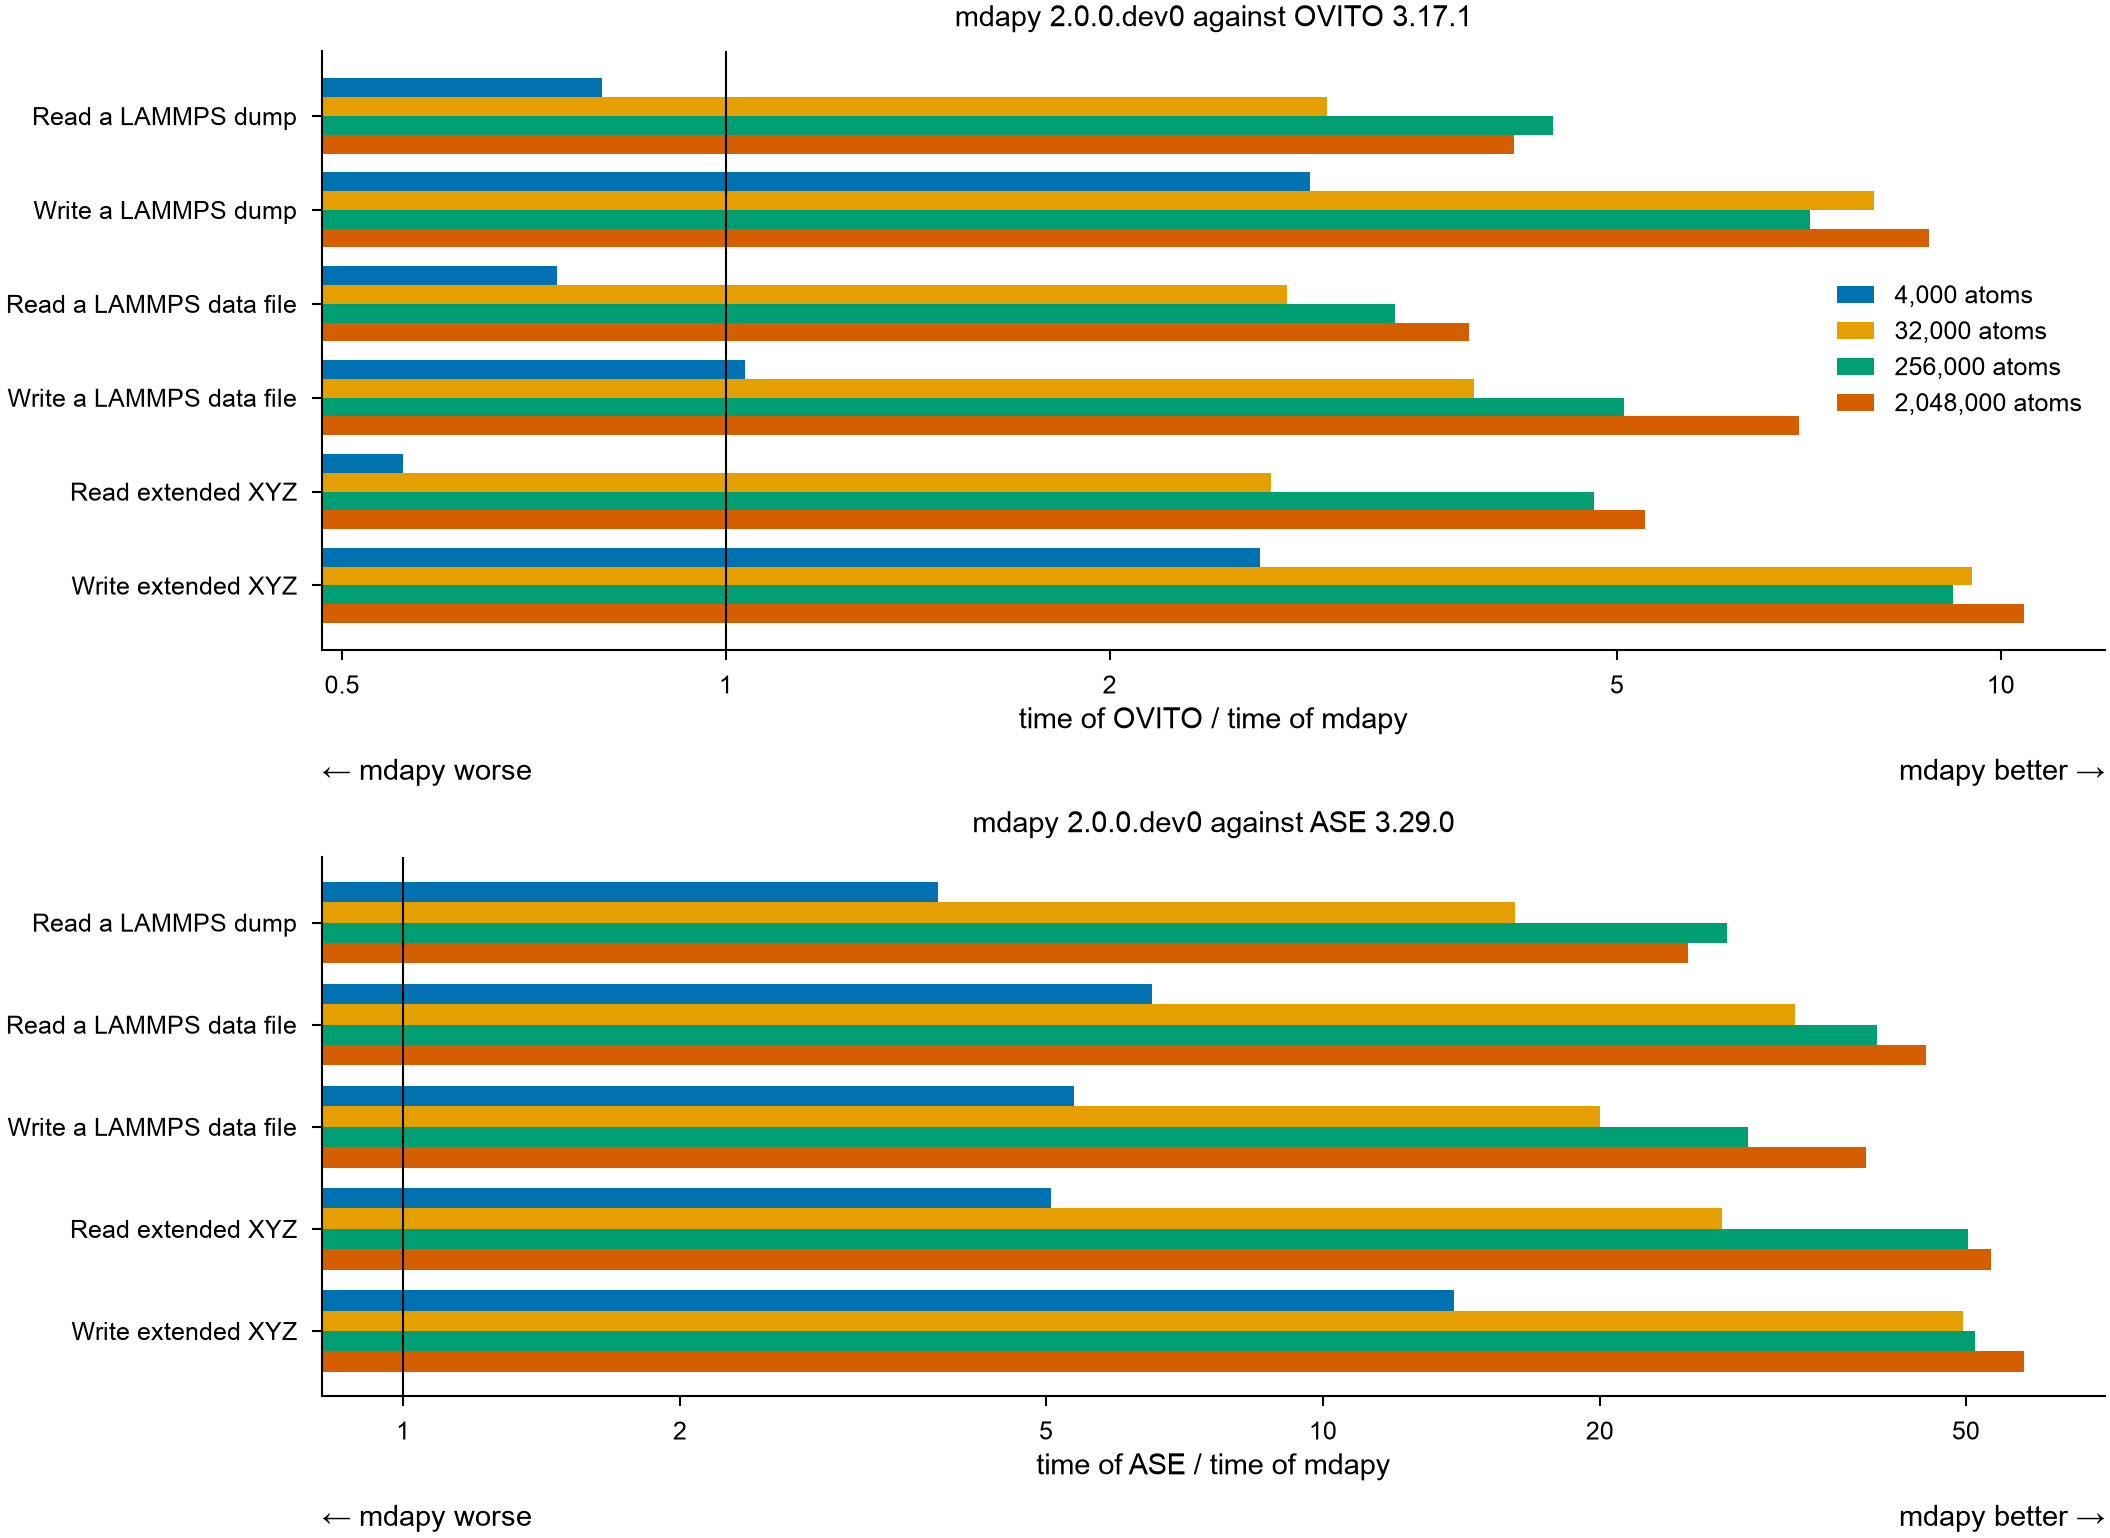
What they show
- OVITO: from 32 000 atoms on, MDAPY reads the three formats 2.7 to 5.3 times faster and writes them 3.9 to 10.4 times faster. At 4 000 atoms OVITO reads faster, in 1.0 to 1.4 ms against 1.3 to 2.2 ms, and MDAPY still writes 1.0 to 2.9 times faster.
- ASE: MDAPY reads 3.8 to 53 times faster and writes 5.4 to 58 times faster. ASE reads a data file of 2 million atoms in 7.7 s and 3.8 GB of memory.
- 2 million atoms take MDAPY 0.08 to 0.17 s to read in each format, and 0.11 to 0.16 s to write with every digit.
Times and memory
Every case at every size: the shortest of three times, and the memory each call took beyond the system, the peak resident memory of the process minus its peak before the timings.
OVITO
| Case | Atoms | MDAPY 2.0.0.dev0 (s) | OVITO 3.17.1 (s) | OVITO / MDAPY | MDAPY (MB) | OVITO (MB) |
|---|---|---|---|---|---|---|
| Read a LAMMPS dump | 4,000 | 0.001 | 0.001 | 0.80 | 0 | 1 |
| Read a LAMMPS dump | 32,000 | 0.002 | 0.007 | 2.96 | 2 | 5 |
| Read a LAMMPS dump | 256,000 | 0.012 | 0.054 | 4.45 | 3 | 7 |
| Read a LAMMPS dump | 2,048,000 | 0.107 | 0.446 | 4.15 | 207 | 141 |
| Write a LAMMPS dump | 4,000 | 0.001 | 0.002 | 2.87 | 0 | 0 |
| Write a LAMMPS dump | 32,000 | 0.002 | 0.018 | 7.95 | 3 | 0 |
| Write a LAMMPS dump | 256,000 | 0.020 | 0.143 | 7.09 | 36 | 0 |
| Write a LAMMPS dump | 2,048,000 | 0.128 | 1.126 | 8.79 | 30 | 0 |
| Read a LAMMPS data file | 4,000 | 0.002 | 0.002 | 0.74 | 0 | 0 |
| Read a LAMMPS data file | 32,000 | 0.004 | 0.010 | 2.76 | 2 | 4 |
| Read a LAMMPS data file | 256,000 | 0.024 | 0.079 | 3.35 | 9 | 4 |
| Read a LAMMPS data file | 2,048,000 | 0.171 | 0.653 | 3.82 | 248 | 69 |
| Write a LAMMPS data file | 4,000 | 0.002 | 0.002 | 1.04 | 0 | 0 |
| Write a LAMMPS data file | 32,000 | 0.005 | 0.019 | 3.86 | 3 | 0 |
| Write a LAMMPS data file | 256,000 | 0.028 | 0.142 | 5.06 | 37 | 0 |
| Write a LAMMPS data file | 2,048,000 | 0.164 | 1.143 | 6.95 | 150 | 0 |
| Read extended XYZ | 4,000 | 0.002 | 0.001 | 0.56 | 0 | 0 |
| Read extended XYZ | 32,000 | 0.003 | 0.007 | 2.68 | 2 | 3 |
| Read extended XYZ | 256,000 | 0.011 | 0.053 | 4.80 | 7 | 0 |
| Read extended XYZ | 2,048,000 | 0.084 | 0.443 | 5.26 | 130 | 3 |
| Write extended XYZ | 4,000 | 0.001 | 0.003 | 2.62 | 0 | 0 |
| Write extended XYZ | 32,000 | 0.002 | 0.020 | 9.49 | 2 | 0 |
| Write extended XYZ | 256,000 | 0.016 | 0.150 | 9.17 | 22 | 0 |
| Write extended XYZ | 2,048,000 | 0.114 | 1.186 | 10.43 | 0 | 0 |
ASE
| Case | Atoms | MDAPY 2.0.0.dev0 (s) | ASE 3.29.0 (s) | ASE / MDAPY | MDAPY (MB) | ASE (MB) |
|---|---|---|---|---|---|---|
| Read a LAMMPS dump | 4,000 | 0.001 | 0.005 | 3.81 | 0 | 0 |
| Read a LAMMPS dump | 32,000 | 0.002 | 0.039 | 16.16 | 2 | 4 |
| Read a LAMMPS dump | 256,000 | 0.012 | 0.332 | 27.50 | 3 | 41 |
| Read a LAMMPS dump | 2,048,000 | 0.107 | 2.680 | 24.93 | 207 | 427 |
| Read a LAMMPS data file | 4,000 | 0.002 | 0.013 | 6.53 | 0 | 7 |
| Read a LAMMPS data file | 32,000 | 0.004 | 0.117 | 32.62 | 2 | 59 |
| Read a LAMMPS data file | 256,000 | 0.024 | 0.942 | 40.06 | 9 | 469 |
| Read a LAMMPS data file | 2,048,000 | 0.171 | 7.723 | 45.23 | 248 | 3793 |
| Write a LAMMPS data file | 4,000 | 0.002 | 0.013 | 5.37 | 0 | 0 |
| Write a LAMMPS data file | 32,000 | 0.005 | 0.097 | 20.03 | 3 | 1 |
| Write a LAMMPS data file | 256,000 | 0.028 | 0.813 | 28.96 | 37 | 1 |
| Write a LAMMPS data file | 2,048,000 | 0.164 | 6.398 | 38.90 | 150 | 0 |
| Read extended XYZ | 4,000 | 0.002 | 0.008 | 5.07 | 0 | 1 |
| Read extended XYZ | 32,000 | 0.003 | 0.068 | 27.17 | 2 | 8 |
| Read extended XYZ | 256,000 | 0.011 | 0.552 | 50.28 | 7 | 56 |
| Read extended XYZ | 2,048,000 | 0.084 | 4.474 | 53.20 | 130 | 534 |
| Write extended XYZ | 4,000 | 0.001 | 0.013 | 13.89 | 0 | 0 |
| Write extended XYZ | 32,000 | 0.002 | 0.102 | 49.65 | 2 | 2 |
| Write extended XYZ | 256,000 | 0.016 | 0.838 | 51.13 | 22 | 5 |
| Write extended XYZ | 2,048,000 | 0.114 | 6.574 | 57.82 | 0 | 0 |
Cases
| Case | MDAPY | OVITO | ASE |
|---|---|---|---|
| Read a LAMMPS dump | mdapy.io.read(path) |
import_file(path).compute() |
ase.io.read(path, format="lammps-dump-text") |
| Write a LAMMPS dump | mdapy.io.write(path, system) |
export_file(data, path, "lammps/dump", columns=[...], precision=17) |
ASE writes no dumps |
| Read a LAMMPS data file | mdapy.io.read(path) |
import_file(path, atom_style="atomic").compute() |
ase.io.read(path, format="lammps-data", atom_style="atomic", units="metal") |
| Write a LAMMPS data file | mdapy.io.write(path, system) |
export_file(data, path, "lammps/data", atom_style="atomic", precision=17) |
ase.io.write(path, atoms, format="lammps-data", atom_style="atomic", masses=True) |
| Read extended XYZ | mdapy.io.read(path) |
import_file(path).compute() |
ase.io.read(path, format="extxyz") |
| Write extended XYZ | mdapy.io.write(path, system) |
export_file(data, path, "xyz", columns=[...], precision=17) |
ase.io.write(path, atoms, format="extxyz") |
The system is fcc copper with its atoms displaced at random by 0.1 Å along
each axis. The dump holds the columns id type x y z; the data file the
atom style atomic, with the mass of copper; extended XYZ the species and the
positions.
MDAPY writes every number with as many digits as it takes to read it back exactly, at most 17. OVITO is asked for 17 significant digits. ASE writes the positions of a data file in full and those of extended XYZ with 8 decimals, so its extended XYZ is about a third smaller.
How it is measured
- Each program runs in a process of its own. MDAPY and OVITO have 40
threads (
MDAPY_NUM_THREADS,OVITO_THREAD_COUNT); ASE reads and writes in Python on one. - Before the timings, a separate process checks each program. Reading: the positions it reads are those MDAPY reads within 1e-12 Å, and the types and elements are the same. Writing: MDAPY reads back the file the program wrote, and finds the positions within 1e-12 Å (1e-8 Å for the extended XYZ of ASE) and the same types and elements. A program that differs is not timed.
- The file to read is written by MDAPY before the timings, so it is in the file cache of the operating system: the times are those of reading and parsing, not of the disk. Writing goes to the local disk of the node as the operating system takes it.
- Each process first reads or writes a system of 500 atoms, so that loading libraries and starting threads are not timed, then three times the system; the shortest time counts.
- Making the system, and converting it into OVITO's data collection or ASE's atoms for writing, are not timed.
Running it
The comparison is benchmarks/comparison.py in the source repository, the
group files of its cases. It needs OVITO (pip install ovito) and ASE
(pip install ase).